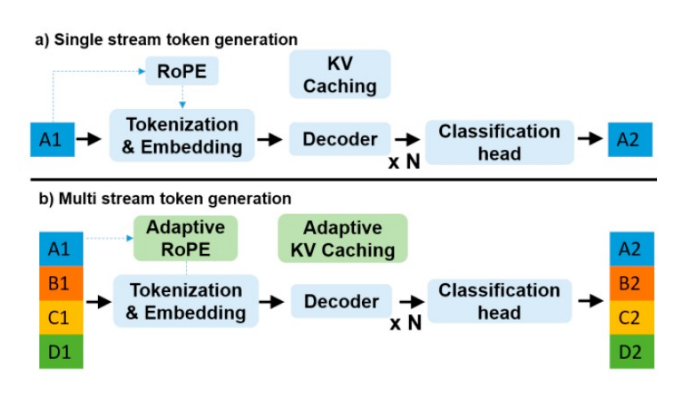
Unlocking the Edge Deployment and On-Device Acceleration of Multi-LoRA Enabled One-for-All Foundational LLM
ACL 2026 Findings of the Association for Computational Linguistics
Training- and inference-time efficiency for vision and language models — from GPU-scale inference to on-device compression.
I work on making models cheaper to train and serve without giving up quality — currently inference optimization on GPUs at Nava, and previously on-device compression at Samsung Research. Below are my publications, patents and thesis. Google Scholar →
ACL 2026 Findings of the Association for Computational Linguistics
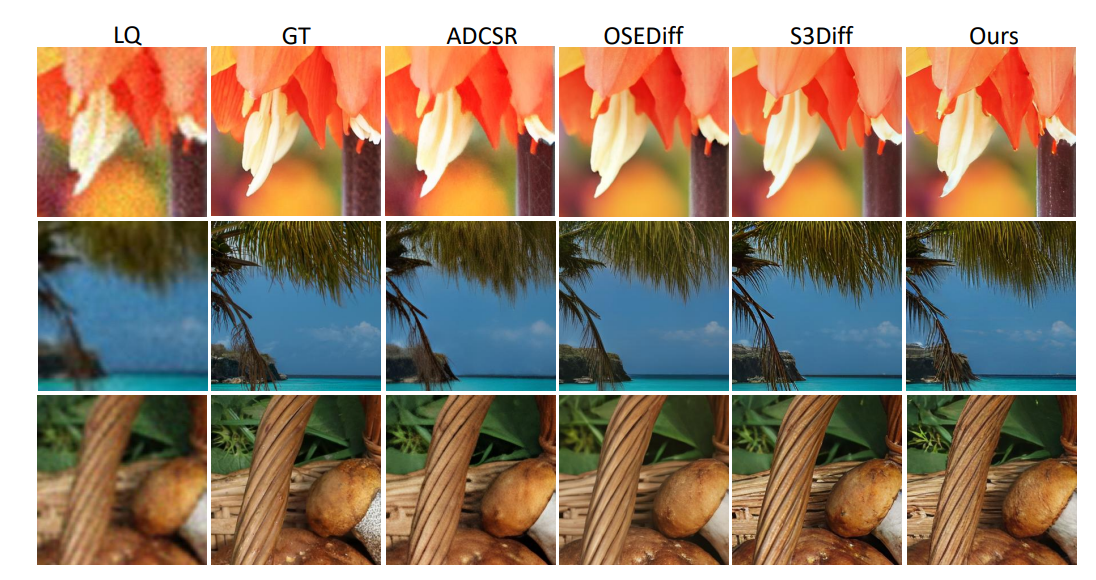
ECCV 2026 W Oral LoViF Workshop, European Conference on Computer Vision
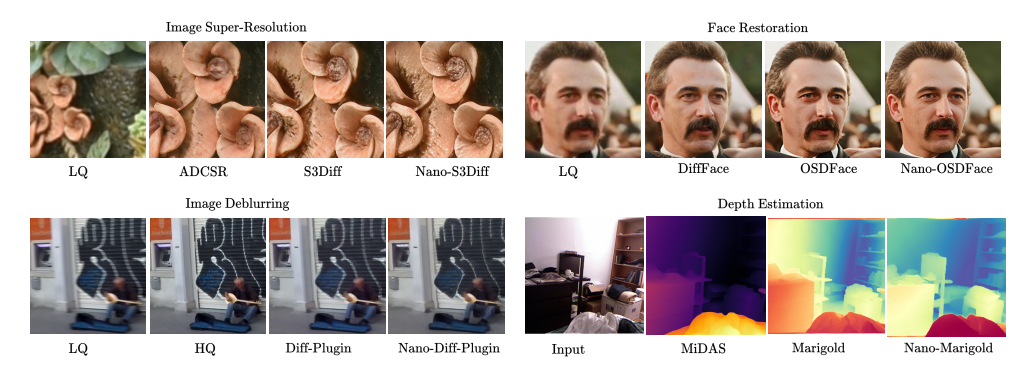
CVPR 2026 IEEE/CVF Conference on Computer Vision and Pattern Recognition
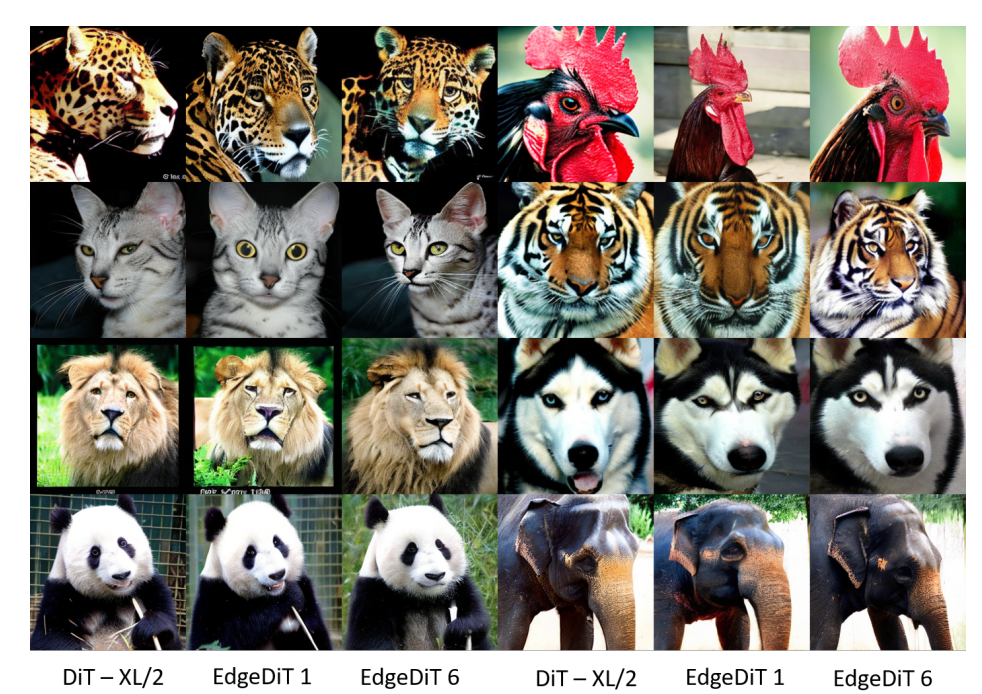
CVPR 2026 W Oral Mobile AI Workshop, CVPR
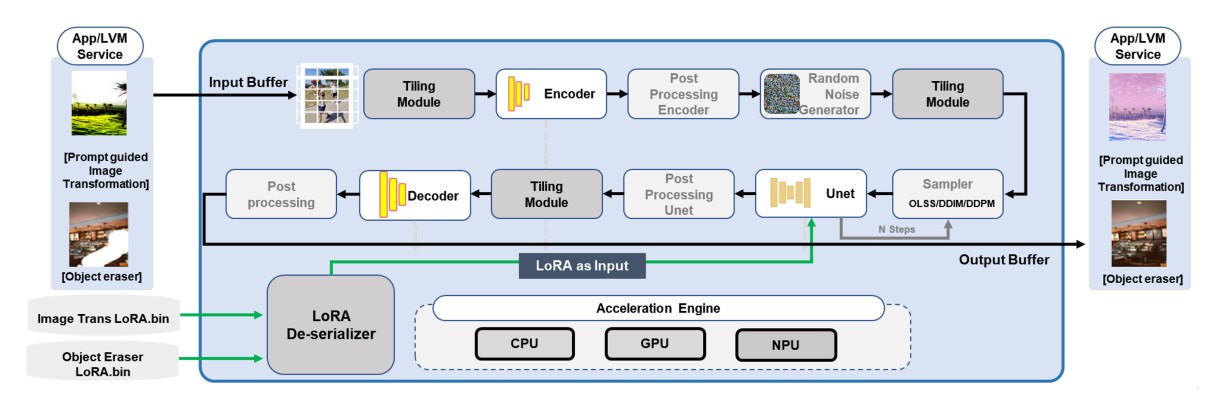
CVPR 2026 W Oral Mobile AI Workshop, CVPR
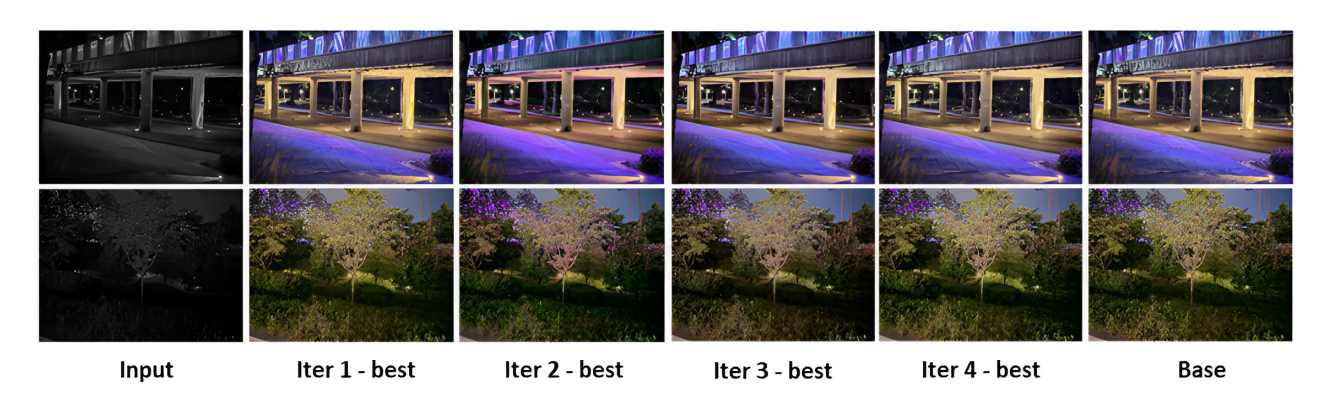
CVPR 2026 W Spotlight Women in Computer Vision (WiCV) Workshop, CVPR
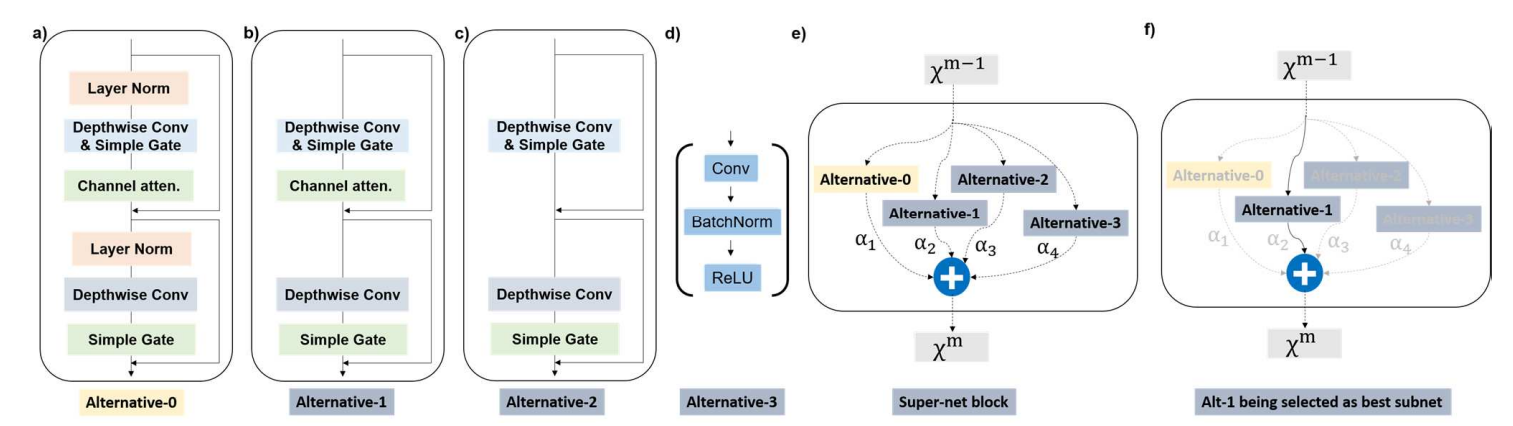
ICASSP 2025 IEEE International Conference on Acoustics, Speech and Signal Processing
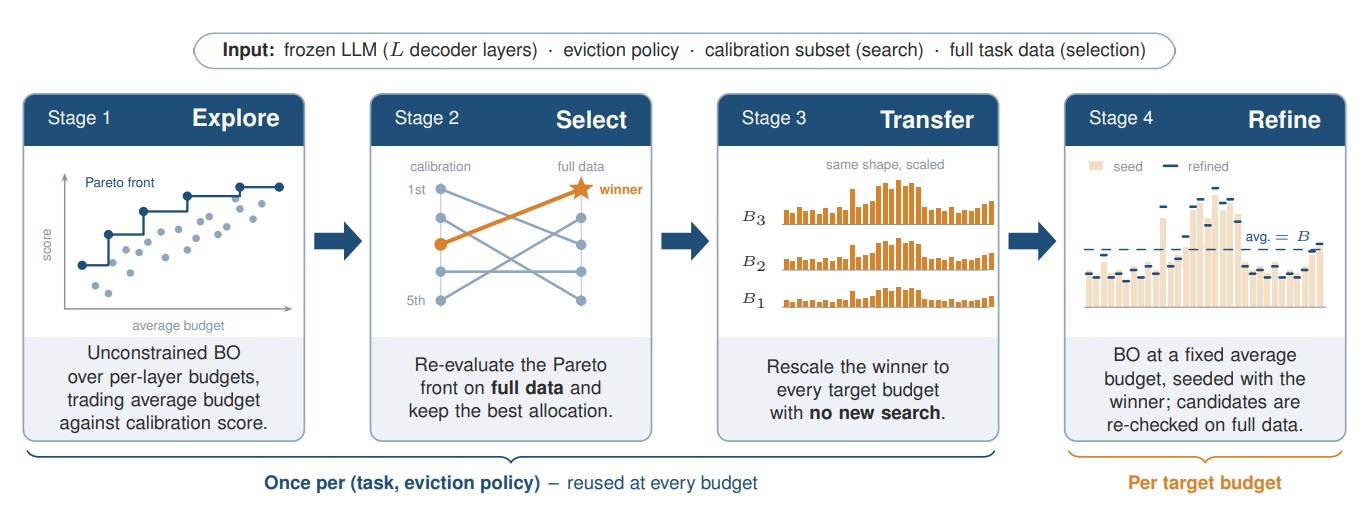
Provisional specification filed
A dynamic sliding window for token-eviction that shrinks the KV cache of LLMs with negligible accuracy loss.
Complete specification filed
A self-speculative decoding technique that improves throughput and reduces latency for on-device LLM inference.